The workflow
Drop audio, get the transcript.
MP3, WAV, M4A, WEBM or OGG in, then pick a model from Tiny at about 75 MB to Distil Large v3.5 at about 530 MB. Edit segments and rename speakers in place.
Browser-based audio transcription with speaker diarisation, for anyone who needs a transcript without sending the recording to a server.
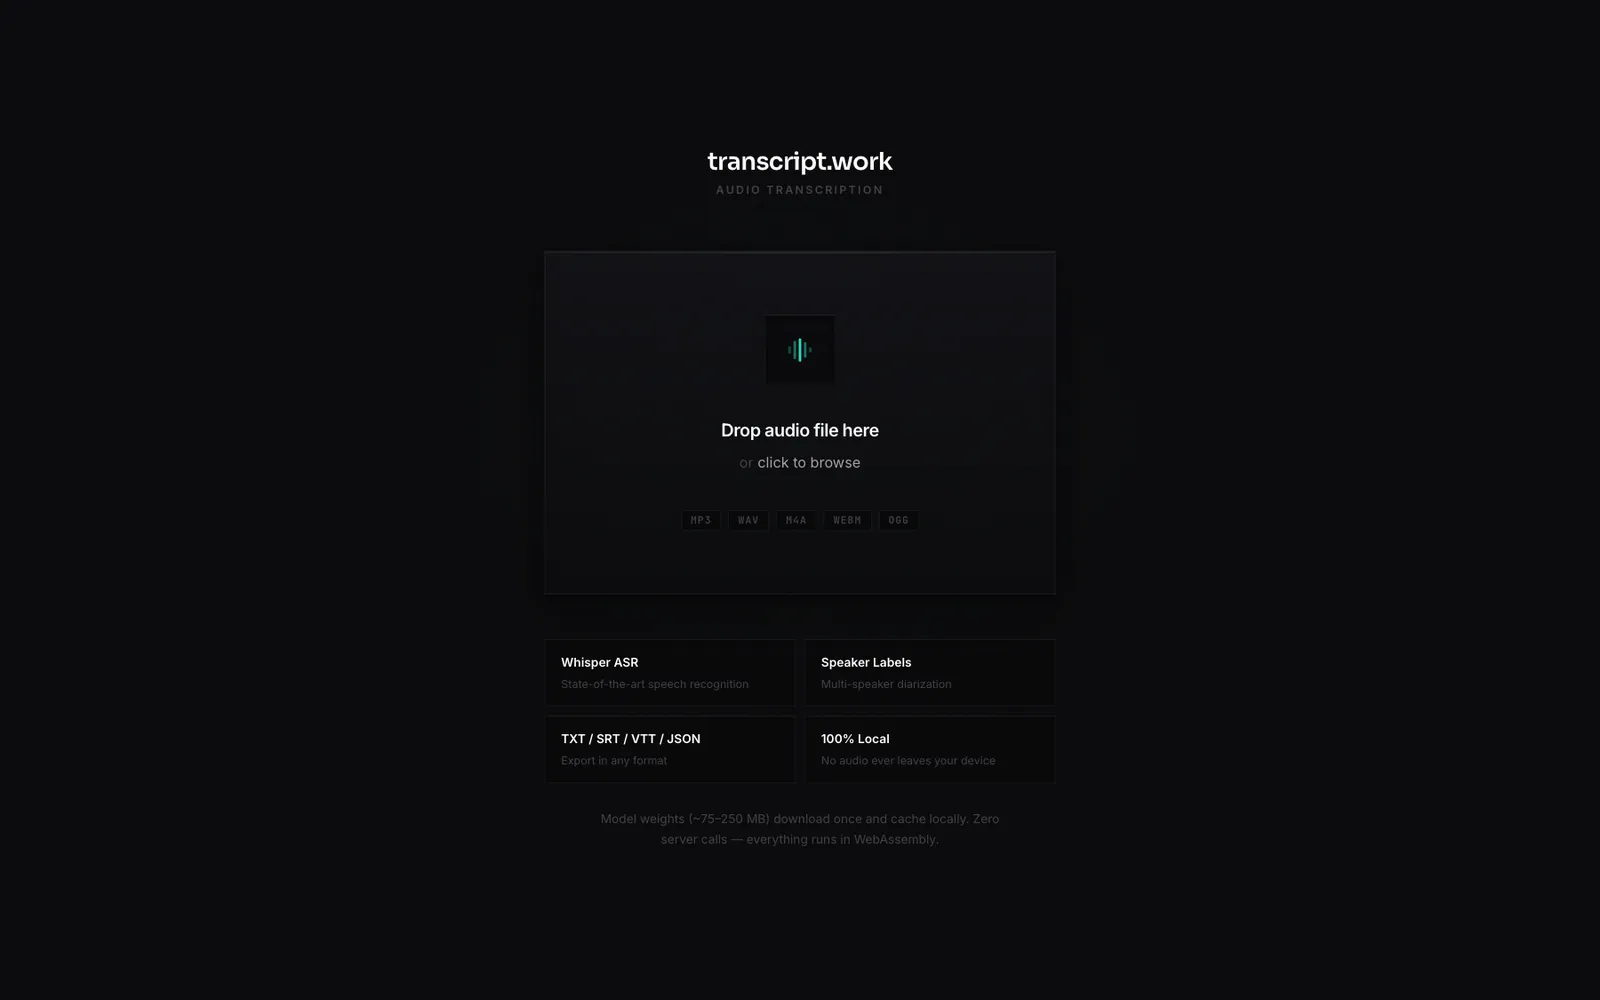
MP3, WAV, M4A, WEBM or OGG in, then pick a model from Tiny at about 75 MB to Distil Large v3.5 at about 530 MB. Edit segments and rename speakers in place.
Whisper runs in a web worker through Transformers.js - on WebGPU where the browser has it, WASM where it does not - and a pyannote model works out who spoke when.
Per-speaker talk time and word counts, speaker turns, silence gaps, interjections and vocabulary richness - then export as TXT, JSON, SRT or VTT.